Ad teams
A complete 30-second spot — footage, voiceover, and music — from one brief, iterated take after take.
Write a line, drop a frame, or hand over a stack of references — you get back up to 30 seconds of finished video with dialogue, music, and lip-synced speech already in place.
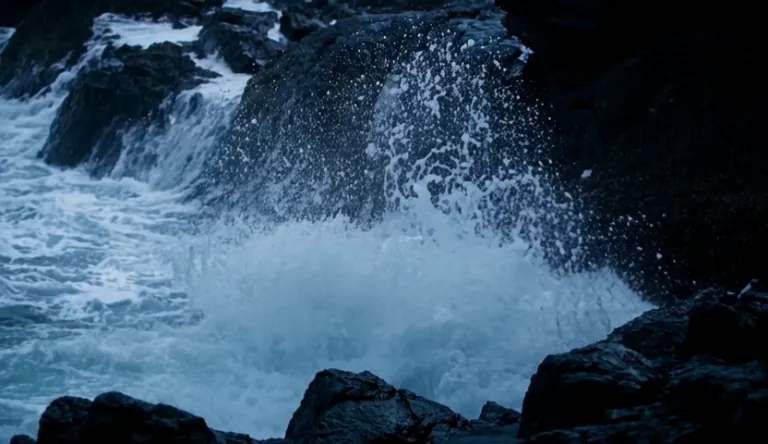
A lighthouse beam sweeps through heavy rain over black rocks at night, waves detonating against the cliff.
Clips from Alibaba's official launch demos — a long single take, character performance, and cinematic scale.
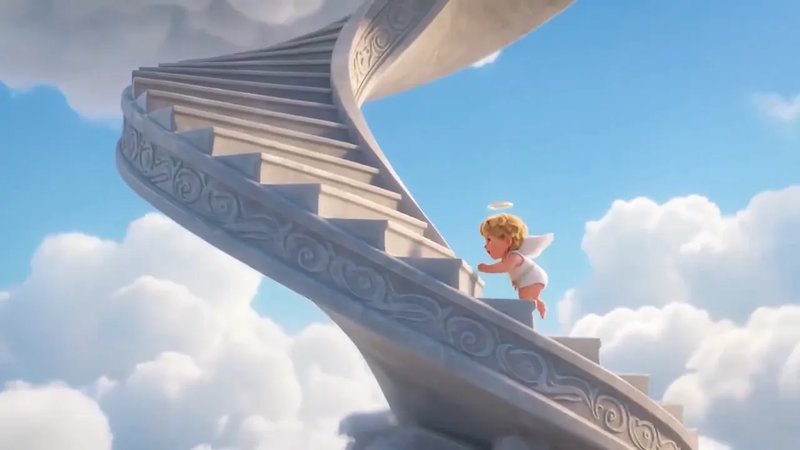
A cherub climbs a spiral staircase through the clouds in one continuous shot — the long, coherent take the model is built for.
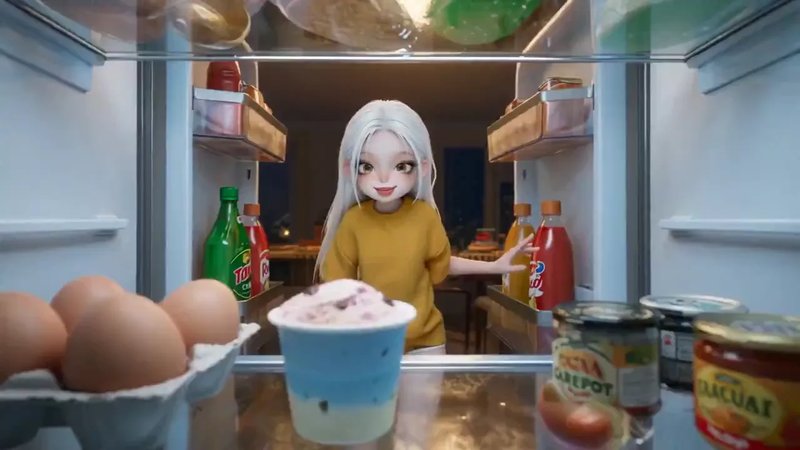
A stylized character raids the fridge at night — expression, motion, and lighting stay consistent through the whole scene.
Lantern-lit ruins, a giant stone Buddha, one warrior — a 30-second cinematic straight out of the model.
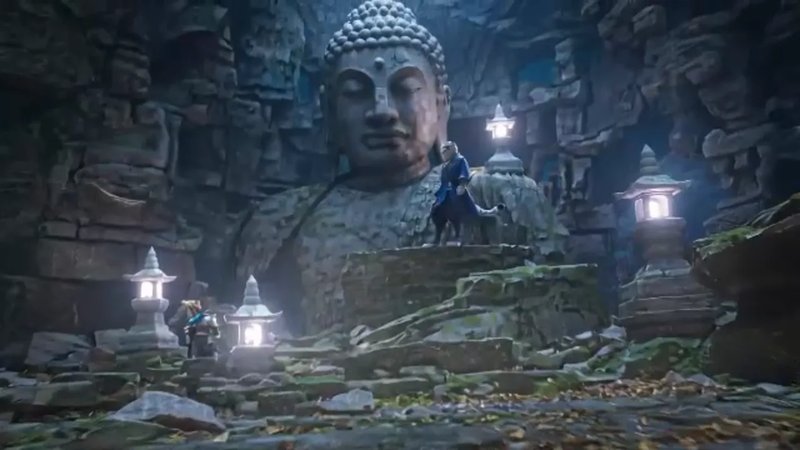
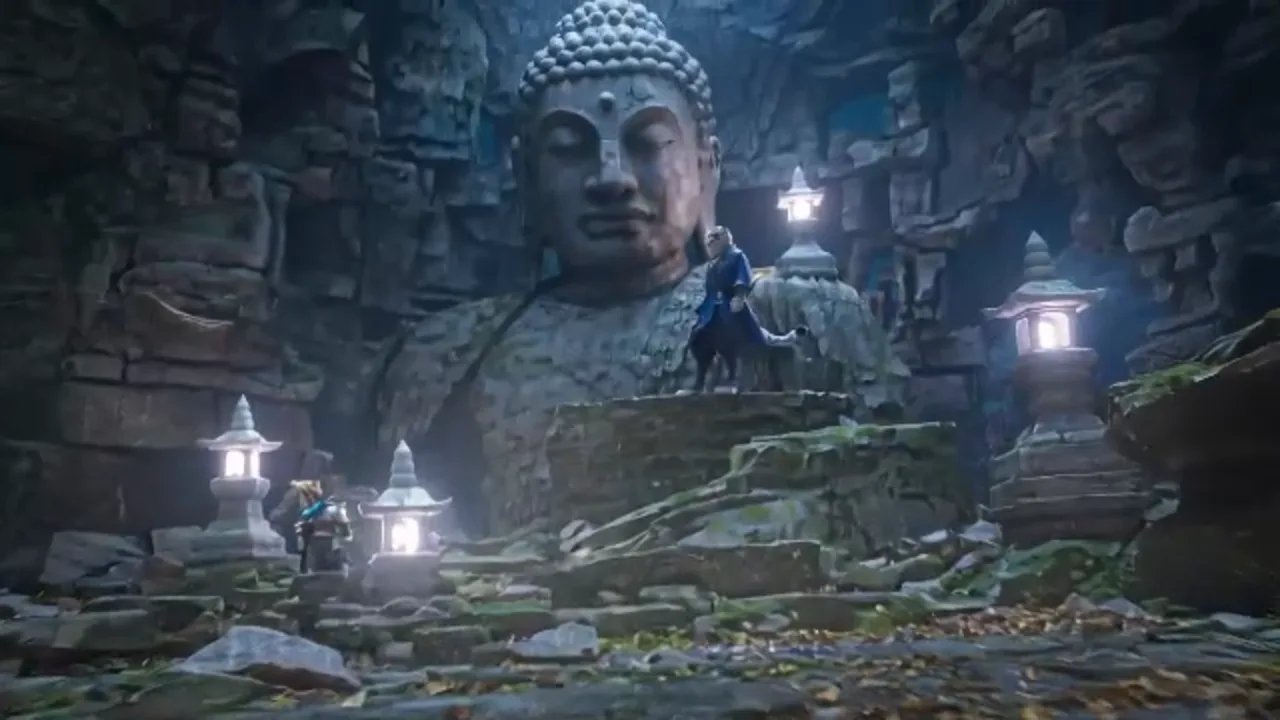
Wan 3.0 is Alibaba's all-in-one video model: text to video, image to video, reference-driven generation, editing, and extension in a single model. Give it a sentence or a first frame and it renders up to 30 seconds at up to 1080p — and because audio is native, dialogue, sound effects, and background music arrive in the same pass, with speech that moves the character's lips. As of September 2026 it sits at #1 on Artificial Analysis' text-to-video (with audio) leaderboard at Elo 1,242, ahead of Gemini Omni Flash and MiniMax H3 Max.
Each mode has its own page with the generator, samples and the settings it takes.
Write the scene, the camera move and a line of dialogue, and get a clip with sound.
Start from one photo or painting and describe what happens next.
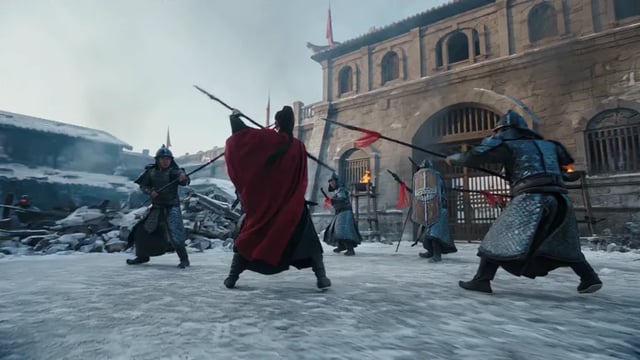
Build one scene from up to 10 images, 5 clips and 5 audio files.
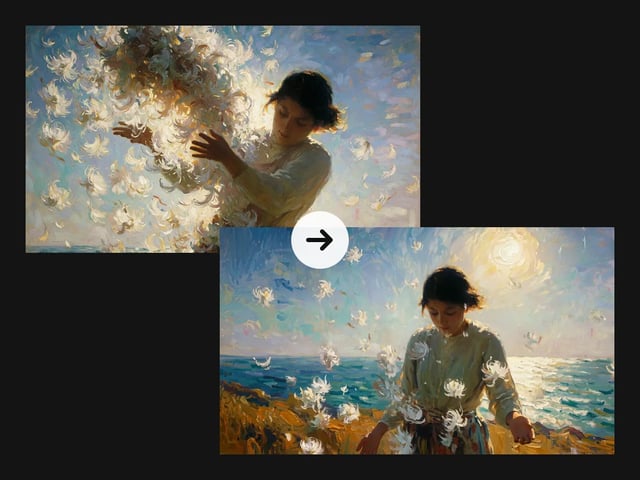
Set the first and last frame, and Wan 3.0 fills in the motion between them.
Pick any whole-second length, with 5 as the default.
Start at 480p while you iterate, then render the keeper at 1080p — every clip runs at a steady 30 FPS.
Dialogue, ambient effects, and music are generated with the picture, and spoken lines drive the lips.
16:9, 4:3, 1:1, 3:4, or 9:16 — or leave the frame on adaptive.
Stack up to 10 images, 5 clips and 5 audio files, and the model builds the scene from all of them.
Pin the opening and closing frames, and Wan 3.0 animates the move between them.
Type what happens — or drop a first frame, an end frame, or a stack of references.
Choose 2–30 seconds, 480p to 1080p, and a frame from 16:9 to 9:16.
The clip comes back with voices, effects, and music in place. Keep it, or adjust the prompt and run it again.
It covers in one pass what used to take a stack of tools.
A complete 30-second spot — footage, voiceover, and music — from one brief, iterated take after take.
Image to video from one hero still: the product shot opens the scene and the model sets it in motion.
Turn diagrams, screenshots and a recorded voiceover into a narrated explainer, without storyboarding it first.
Vertical 9:16 scenes with dialogue that lip-syncs — with the dialogue already audible — ready for the feed.
Cinematic sequences with consistent characters, staged shot by shot and extended scene by scene.
What changed from the Wan 2.7 API line, per Alibaba's launch announcement.
| This siteWan 3.0The all-in-one generationGenerate | Wan 2.7Previous API generation | |
|---|---|---|
| Longest single pass | Up to 30 seconds | Capped at 15 seconds |
| Model shape | Reference, editing, generation, and extension in one model | Split across separate models |
| Inputs | Text and frames, plus up to 20 reference images, clips and audio files | Narrower input set |
Subscriptions load your account with credits — $19.90 loads 1,000: 25 five-second drafts, or 6 ten-second 720p takes.
Up to 500 images or 41 videos
Up to 1,250 images or 104 videos
Up to 3,750 images or 312 videos
· No card required
Failed runs are refunded automatically · Cancel anytime
2 to 30 seconds in a single pass, with 5 as the default. You set the length before you generate.
Yes — dialogue, ambient effects, and background music render natively in the same pass, and spoken lines drive the character's lip movements.
Yes — image to video starts from one frame, or pin both the first and last frames and the model fills the motion between.
Images, video clips and audio: up to 10 images, 5 clips (15 seconds in total) and 5 audio files in one generation. On Reference to video, call them Image1, Video1 or Audio1 in your prompt.
No — output is 480p, 720p, or 1080p at a fixed 30 FPS. 1080p is the ceiling; the generator opens at 480p so drafts stay cheap.
No — it's a paid, hosted model. Plans start at $19.90 a month for 1,000 credits; a render costs by the second, so a five-second 480p draft is 40 credits and a ten-second 720p take is 150.
No — this generation is Alibaba's hosted API model. Alibaba hasn't released 3.0 weights — the downloadable open-source models stop at Wan 2.2 — so the 3.0 generation runs through a hosted generator like this one.
Keep the take, or change the prompt and run it again — your first scene is one prompt away.